今日从 arXiv 订阅中筛选 10 篇论文。
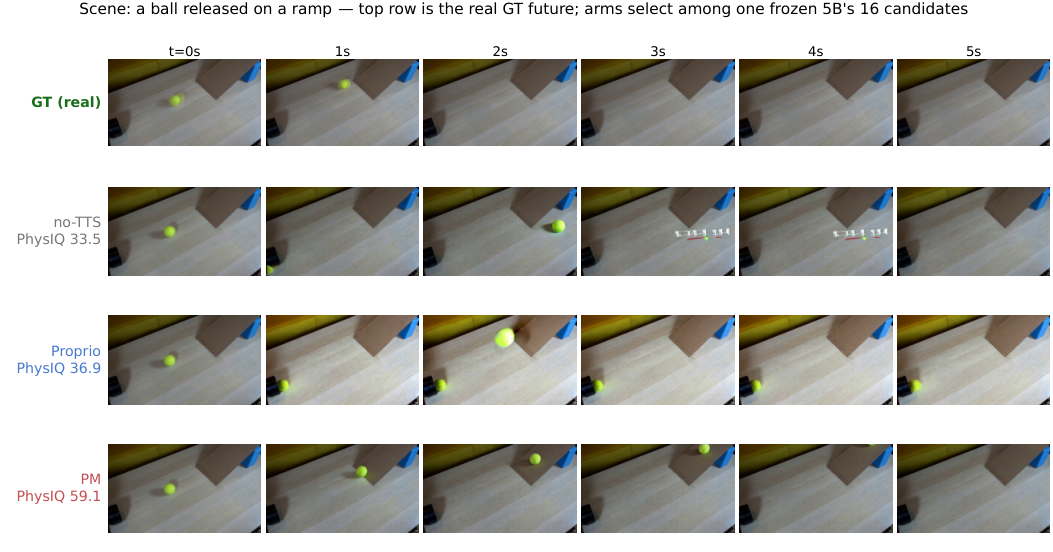
⚡ Sampling headroom is not selection gain: a compute-value audit of test-time scaling for video world models
test-time scaling 的 compute-value 审计:sampling headroom ≠ selection gain。
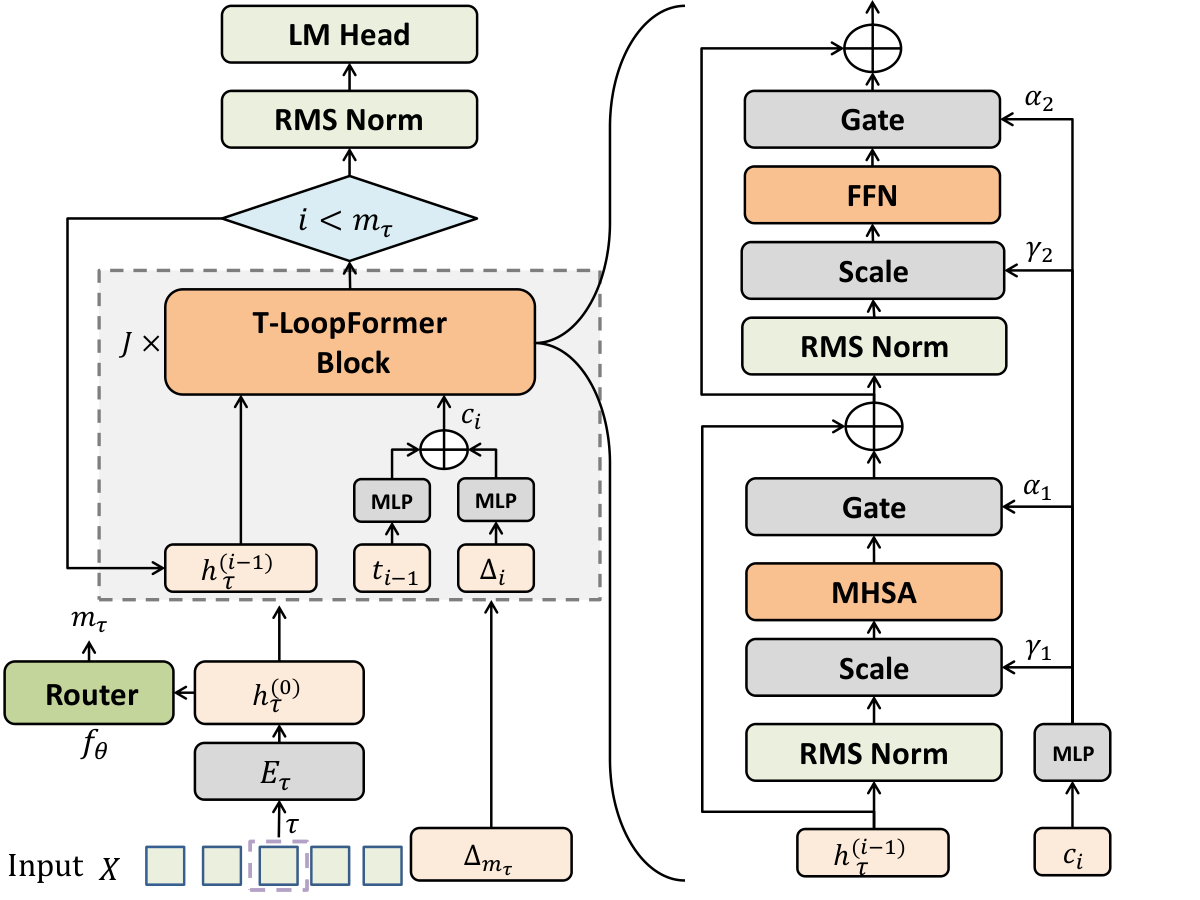
⚡ T-LoopFormer: Token-Level Elastic-Depth Looped Transformers for Latent Reasoning With Dynamic Routing
looped Transformer 的 token 级弹性深度:简单 token 早退、难 token 深递归。
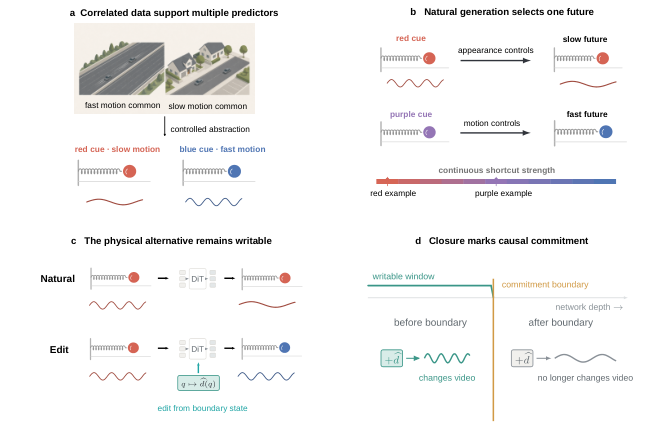
⚡ A Chosen Future Can Still Be Rewritten: Causal Writability in Video Models
视频模型的 causal writability:物理错误是"没学到"还是"学到但没用"?答案:后者。
⚡ How Many Thoughts Can a Vector Hold? The Capacity of Reasoning by Superposition
一个向量能装多少 thought:latent 推理的叠加容量理论。
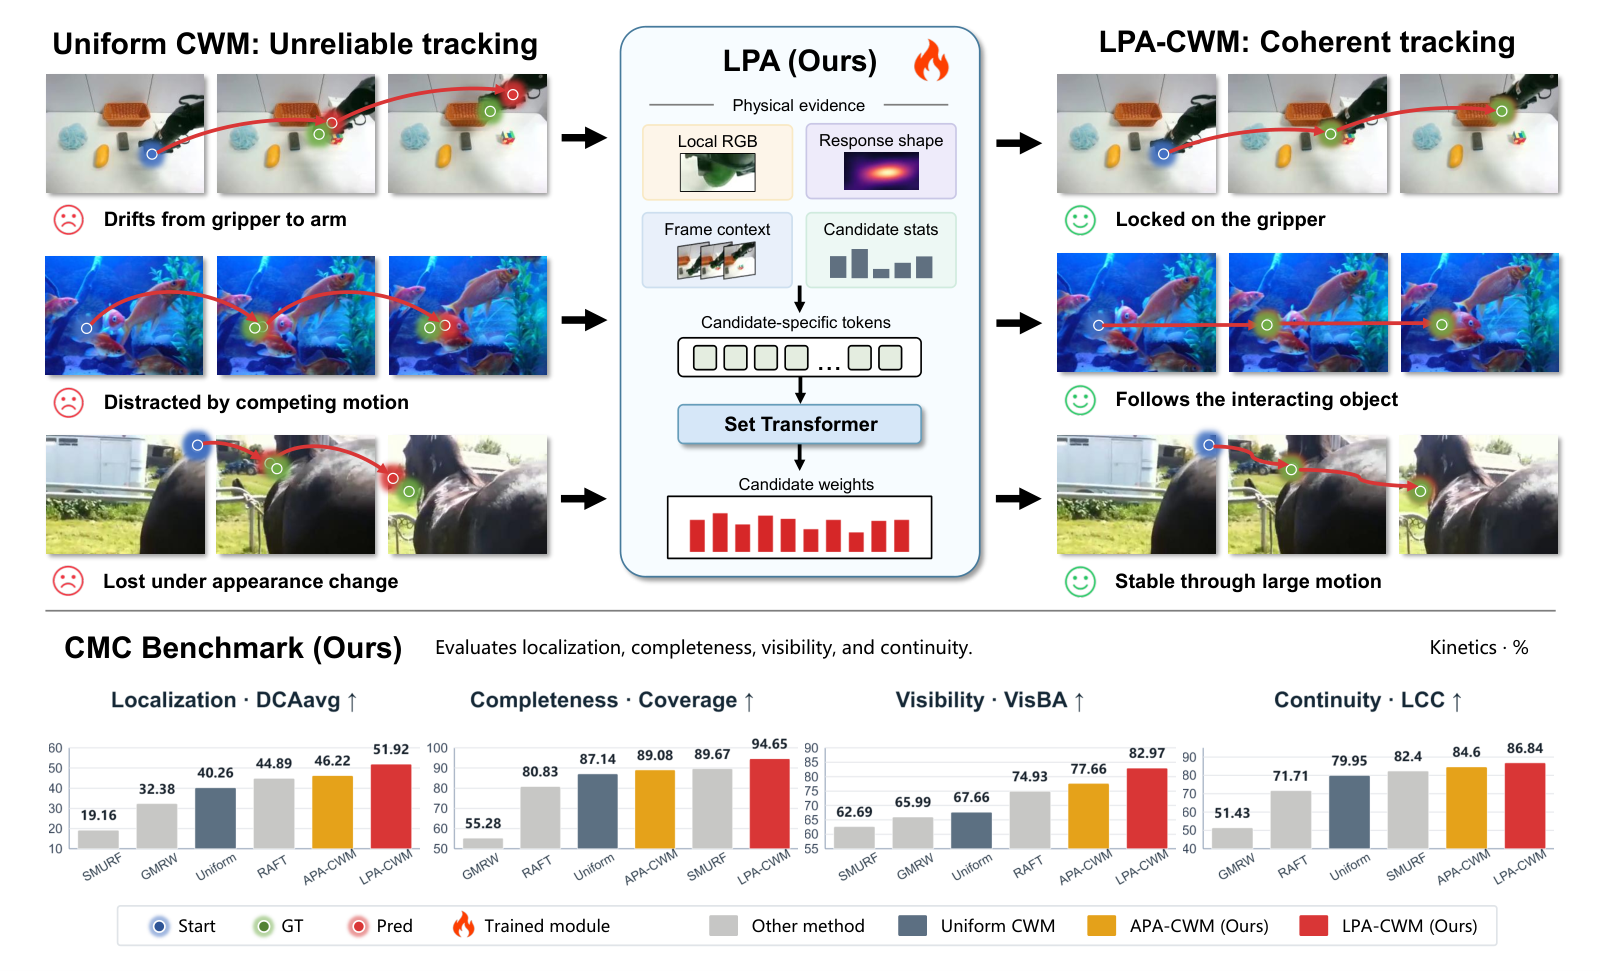
⚡ LPA-CWM: A Learned Physical Adjudicator for Motion Reasoning with Counterfactual World Models
反事实世界模型的"物理仲裁者":学会给不同干预响应加权。
⚡ Diagnosing Faults in Reinforcement Learning Simulators and World Models with Canonical Polynomial Invariants
物理结构到底帮不帮预测:精确不变量测试"物理结构有益论"。
⚡ GRAVA: Grounded Reasoning-to-Action Representation and Learning for Autonomous Driving
驾驶 VLA 的 grounded reasoning-to-action:推理必须锚回场景证据与可执行动作。
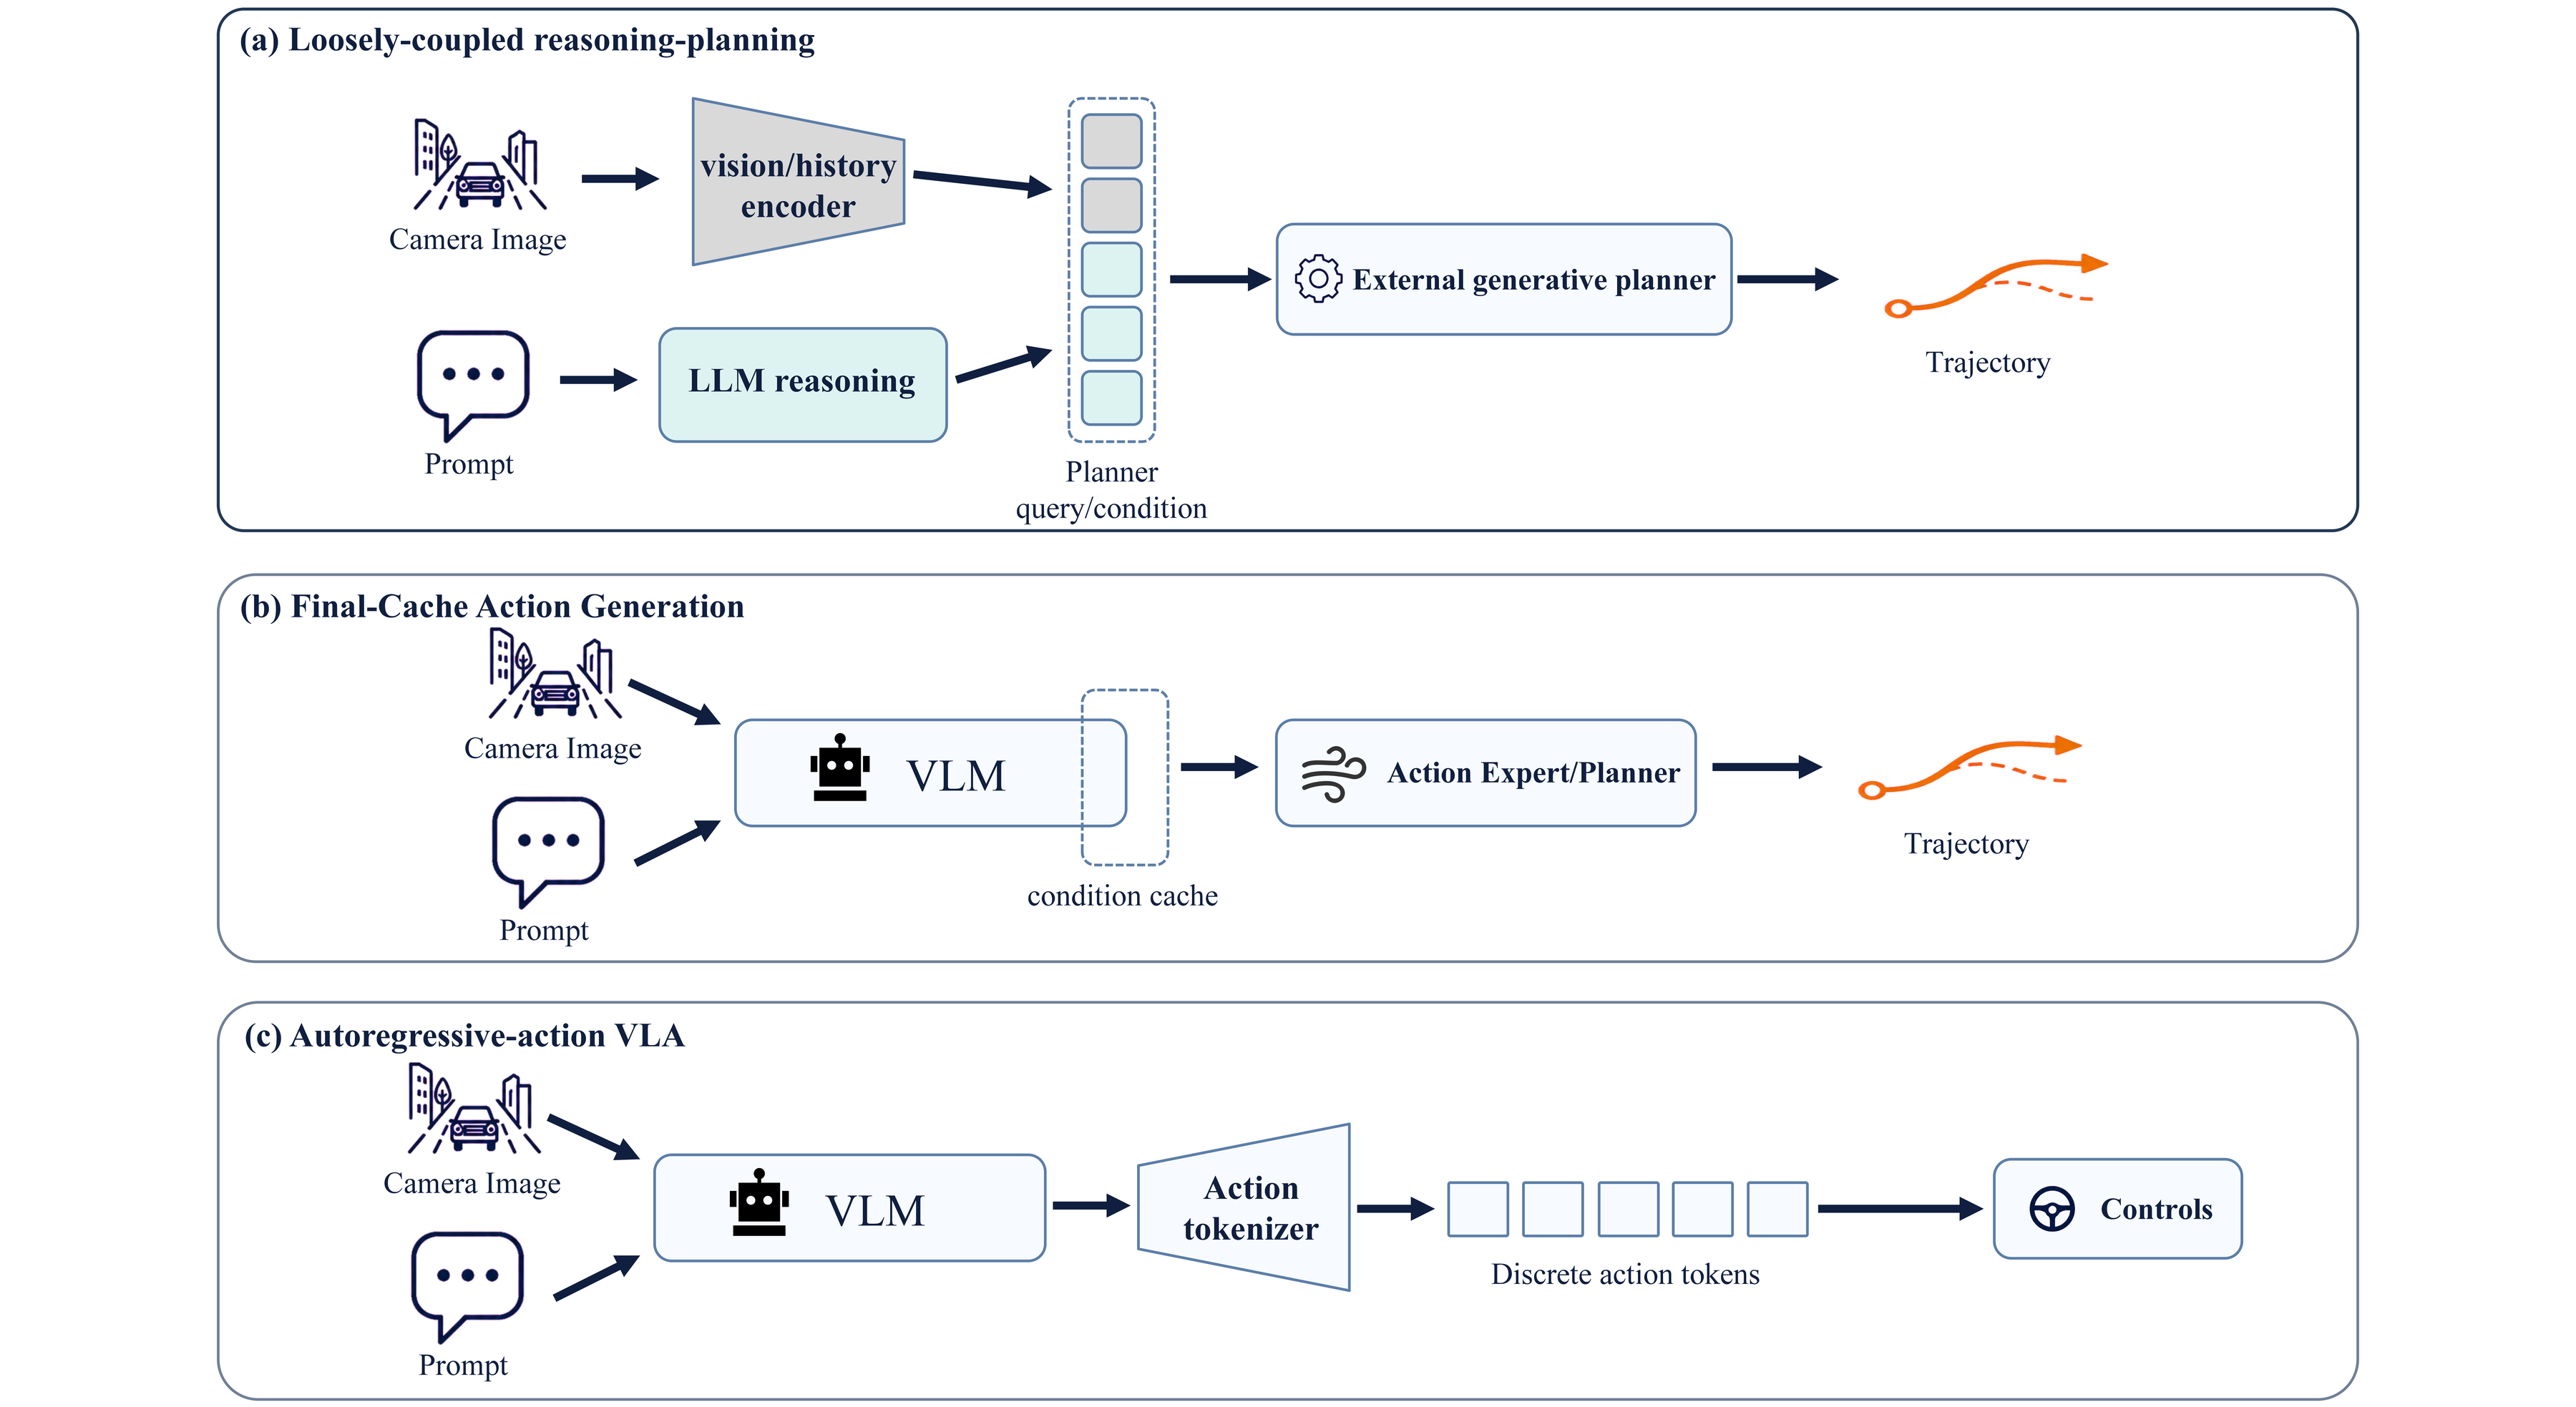
⚡ Planning in the Backbone: DiffAdapterVLA for Native Continuous Trajectory Generation with Driving VLMs
Planning in the Backbone:把轨迹生成放进驾驶 VLM 的主干计算里。
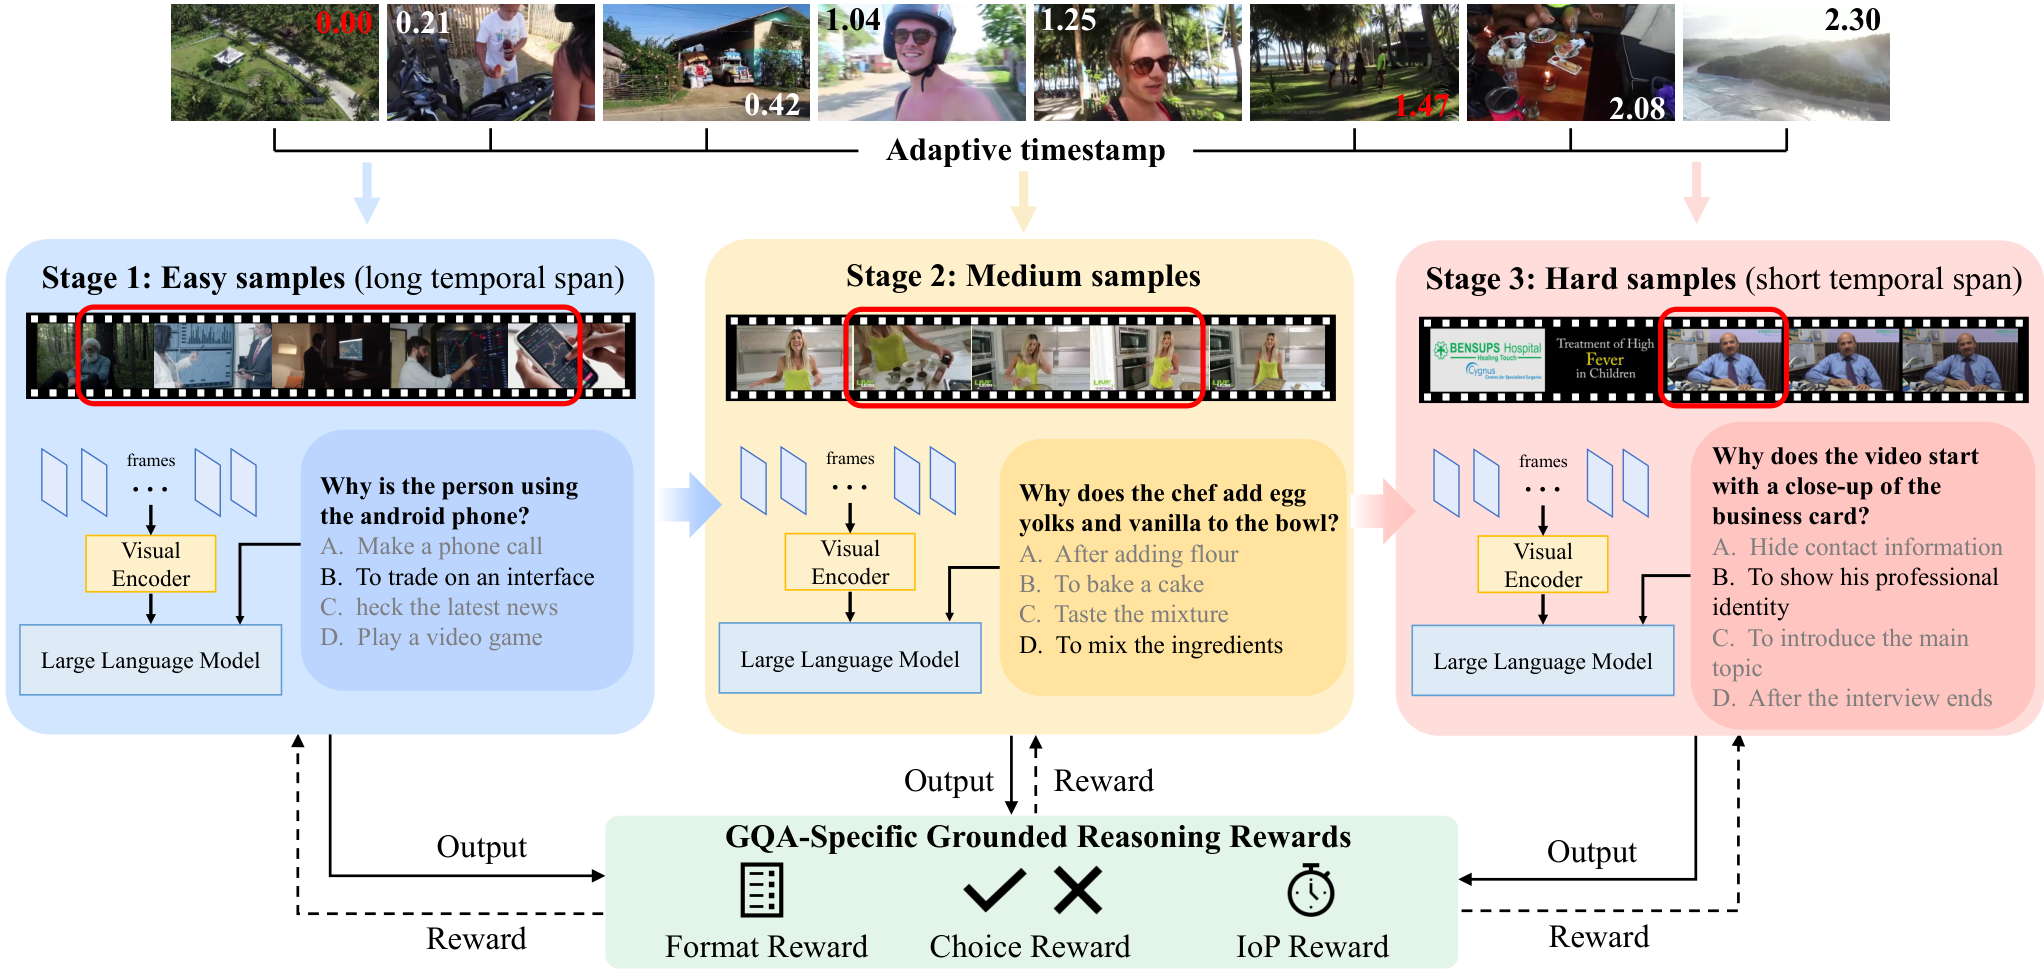
⚡ Long-to-Short Video Evidence Reasoning for Grounded Question Answering
长到短视频证据推理:按证据时长组织课程,IoP 替代 IoU。
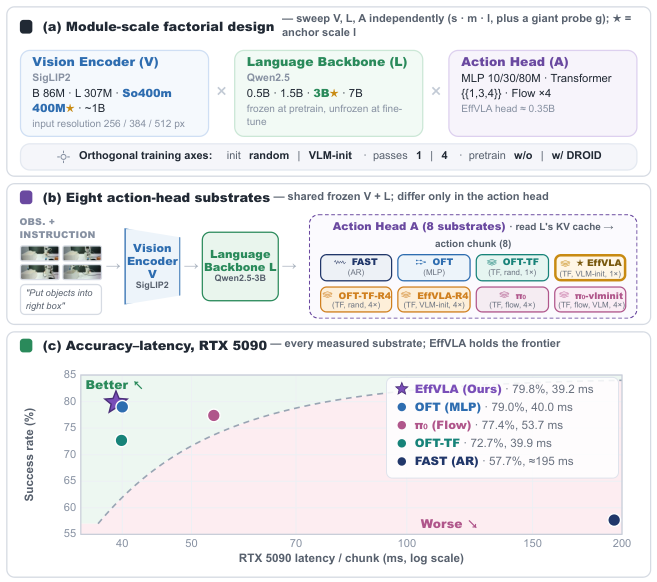
⚡ What Makes an Efficient VLA? Navigating Action-Head Design, Scaling, and Latency
什么让 VLA 高效:action-head 的初始化对齐 > 架构设计。
自动生成于 2026-09-16 · 基于 arXiv Daily Digest